
Development documentation may include features that are not in the latest release. Read the Lawn 0.8.1 guide.
Field guide
Introduction
Run AI models locally and expose them to your self-hosted apps.
Inference providers
Local inference is currently in private alpha. It will be released publicly once the API has stabilized.
Lawn acts as an inference broker for your self-hosted apps. Define providers — local models, machines on your network, cloud APIs — and Lawn routes each request to the right place. One endpoint for your apps, full control over where inference happens.
What to expect
- Define your providers — configure local models, cloud APIs like OpenRouter, or machines on your network as inference providers, all in one place
- Hardware acceleration — models run on your Mac's GPU using MLX and Metal
- Distributed inference — utilize local clusters to spread the load across machines on your network, including NVIDIA GPUs on Linux
- Exposed to containers — containerized apps call a single endpoint, Lawn handles the rest
- Inference routing — route requests to local models, remote machines, or cloud providers — you control which requests go where
- Your rules — keep everything local, use the cloud as a fallback, or mix and match per app
How it works
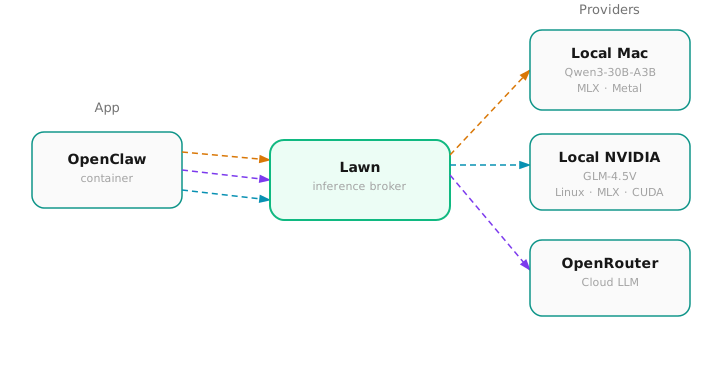
Apps make inference requests to Lawn's local broker, which routes them to a local model running on Apple Silicon or to a cloud provider like OpenRouter — all behind a single endpoint.
Example setup
An OpenClaw instance routing inference across three providers — a local Mac running Qwen3, a Linux machine with an NVIDIA GPU running GLM-4.5V, and OpenRouter as a cloud fallback.
Continue reading